Output vs outcome: Judge engineering by what customers can now do, and tell the board
You shipped more this quarter than last. Your customers are no better off. Which number is the work actually being judged on?
Again, find the axis where your claimed pole and your lived pole pull apart, then give yourself to that analysis. If output-versus-outcome is already the tension eating your quarter, this is your chapter. If it isn’t, read it lightly and save your energy for the axis that is.
Chapter 8 argued for subordinating the non-constraints. That pays off only when the constraint serves the right number. Output and outcome are different numbers, and the gap between them is where feature factories live.
The two poles
Pole A: output. The unit of management is velocity, units shipped, features released, work completed.
Pole B: outcome. The unit of management is customer progress, market position, mission impact.
This axis is well known among engineering leaders. The vocabulary—feature factory, output vs outcome, customer progress—has been in circulation for well over a decade.
Where Pole A is right
Pole A is right when output and outcome have been shown to track each other tightly in the relevant domain. In a sales organisation with a mature product, deals booked may convert predictably to revenue over months. In a fulfilment operation, units shipped may equal customer demand met, provided return rates remain low and margins stable, and in a regulatory pipeline, filings submitted may track approvals secured when the regulator’s response time is well-characterised over multiple cycles.
The metric I was judged on was velocity. Wherever it became the watched number, estimates grew to meet it; I once saw a team carrying a velocity in the hundreds, the number climbing while nothing shipped any faster. Metrics like these earned their place first: deals booked, units shipped, and features released were proxies that tracked the customer outcome closely enough that managing the proxy amounted to managing the outcome.
None of that discipline was wasted. Counting output is part of what makes anything ship at all. A team that can’t count what it has produced can’t tell learning from activity.
Pole B doesn’t abandon counting. It asks you to notice when output stops tracking the outcome.
Where Pole B is right
Pole B is right whenever the firm produces more output and gets worse outcomes. This is the empirical pattern in feature-factory product organisations. The velocity’s high and the customers still leave. In one adoption I coached, the teams had been quick before the change, but they were building the wrong product quickly. Afterwards they were slower, and the quality was better at the end. Pole B costs the leader something real: standing in front of a falling output number on purpose.
In Clayton Christensen’s Jobs to Be Done theory, laid out in Competing Against Luck, the customer isn’t buying your feature. The customer is hiring your product to make progress on a job.
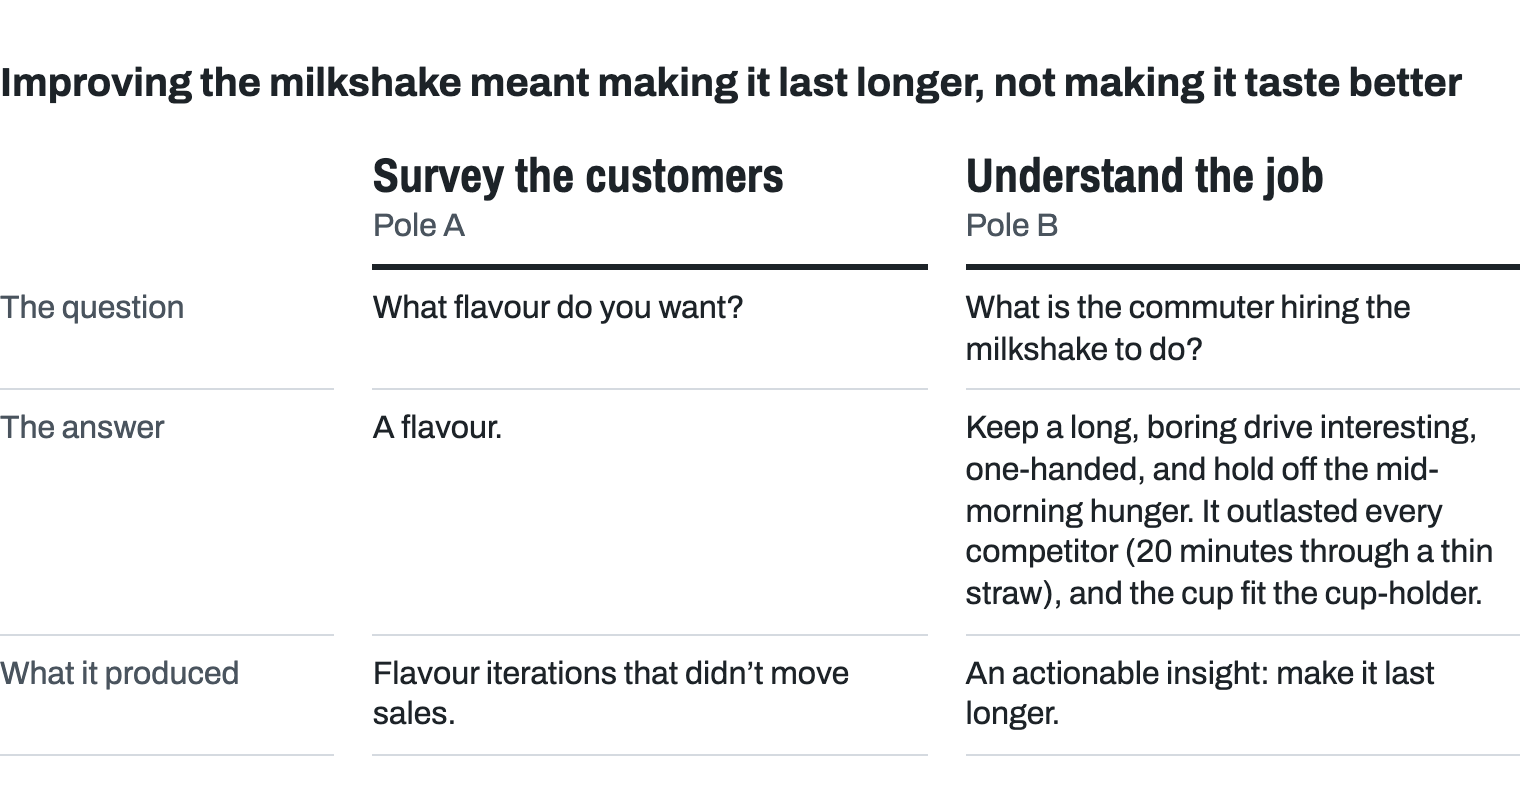
The classic example is the milkshake a fast-food chain sold in surprising numbers before 9 a.m. to commuters buying nothing else. Commuters hired the milkshake to keep a long, boring drive interesting, one-handed, and to hold off the mid-morning hunger. The milkshake was hired because it outlasted every competitor—a thick shake takes 20 minutes through a thin straw—and the cup fit the cup-holder.
Improving the milkshake meant making it last longer, not making it taste better. The Pole A move (survey the customers, ask how to improve the shake: cheaper, chunkier, chocolatier) produced changes that didn’t move sales. The Pole B move (understand the job) produced an actionable insight.
Marquet: redwork and bluework
David Marquet’s Leadership Is Language names an operational discipline that fits the output-outcome distinction. Redwork is execution under pressure: doing what has been decided. Bluework is judgement and pause: deciding what to do.
The Industrial-Age inheritance divided planning from doing. A few people decided; everyone else executed. Marquet recasts those activities as bluework and redwork, then argues that work now requires everyone to do both.
In Marquet’s terms, the language of prove and perform gives way to the language of improve and learn.
The Pole A leader who manages to features-shipped runs in pure red mode. The team decomposes the goal into tasks, executes them, and reports completion. Bluework has no place to happen because the language of the work has no opening for judgement.
The Pole B leader inserts bluework into the cadence. The team pauses, checks whether the output delivered the outcome it was meant to serve, and changes the next round of redwork based on what it learned.
We committed to ship X by Q3 closes the loop on redwork. We hypothesised that shipping X would produce outcome Y by Q3; what did we learn? opens the loop into bluework.
Marquet’s own protocol on the USS Santa Fe, replacing “request permission to…” with “I intend to…”, moves the judgement to the person closest to the work; chapter 17 runs it in full. The leader states what military doctrine calls commander’s intent: a plan that specifies the steps dies the moment events outrun it, and the statement that survives is the goal and the end-state, compact enough that people down the line can improvise toward it.
Innovation accounting
Eric Ries’s accounting discipline for Pole B distinguishes vanity metrics, which rise regardless of whether anything is working, from actionable metrics, which show clear cause and effect, so you know what to do next.
Here’s the test I use to tell them apart, built on Douglas Hubbard’s point that a measurement earns its keep only if it could change a decision. Pick the metric. Predict what it will do over the next two weeks or months. Look at it. Did the prediction match? If it didn’t, what would you do differently?
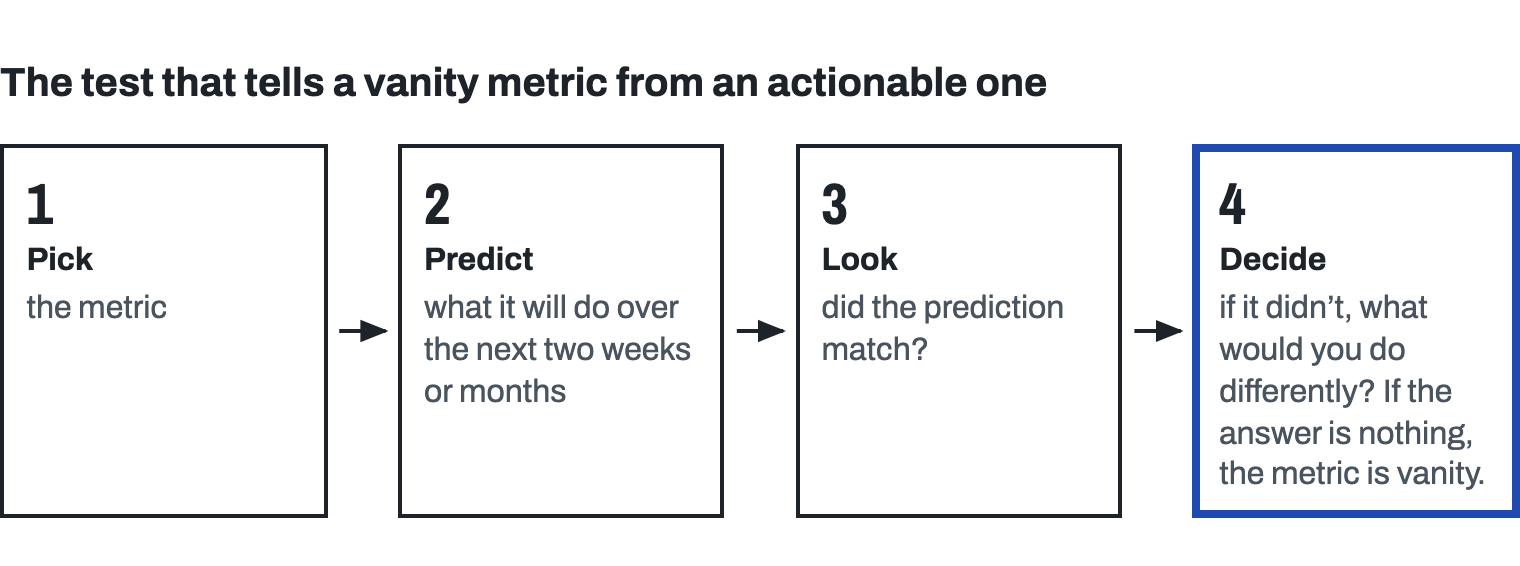
If the answer to that last question is nothing, or you can’t say what moved the number, the metric is vanity: you’re not running on data, you’re running on its appearance.
On StubHub’s recommendations engine, where I was product lead in 2013, we built telemetry in from the start. We tracked whether people clicked on recommendations and whether those who clicked converted at a higher rate, and we A/B tested recommendations on the home page and similar surfaces to see what showing them did to overall conversion. As I remember it, those results justified keeping recommendations across the site and building more of them.
Innovation accounting, Ries’s system of learning milestones for measuring validated learning against the investment, converts Pole B into language the Pole A board can use without losing accountability. It is the chapter-7 board script again: commit to learning a named thing, by a date, at a cost, then report what was learned and what to test next.
Cagan: valuable, usable, feasible, viable
Marty Cagan’s four big risks, the simplest test I have seen for product work, ask whether a feature is valuable, usable, feasible, and viable; he wants them answered in discovery, before the team builds.
Valuable means it produces an outcome the customer cares about. Usable means the customer can access that value. Feasible means the team can build and operate it within the firm’s constraints. Viable means the business itself can sustain it.
A Pole A team may optimise for feasible, building what it can build and shipping features that are technically clean but irrelevant to customers. The most user-research-heavy teams sometimes over-rotate on valuable and ship features the team can’t operate at scale.
A feature is worth shipping only if it meets all four. Run the four-part test on last quarter’s releases and count how many clear all four.
Edmondson’s intelligent failure
Fail fast becomes operational only when a failure meets Edmondson’s four criteria for an intelligent failure, which chapter 10 walks in full. Until then it is a slogan a Pole A leader can adopt while keeping the old metrics: failed experiments per quarter is an output number too, and it passes the vanity test no better than features shipped.
A representative case
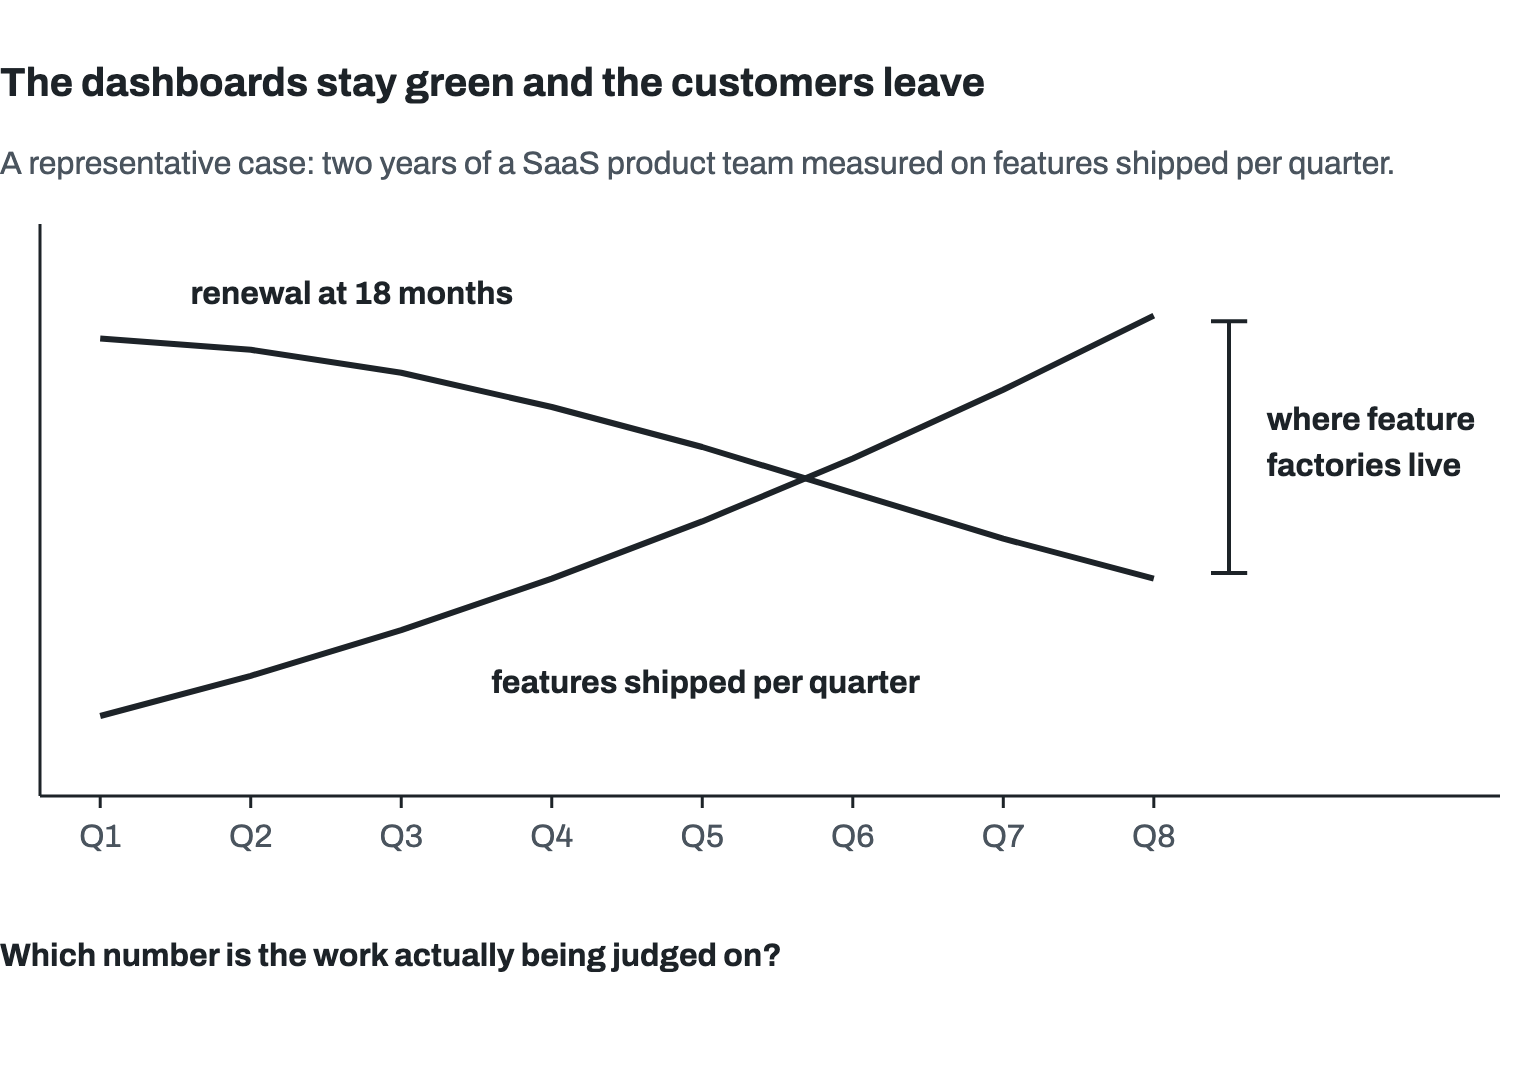
Picture a SaaS product team that has been measuring features shipped per quarter for two years. The number goes up steadily. The customer churn rate also goes up steadily.
The CEO can’t reconcile the two numbers. Engineering leadership points at the customer success function; the customer success function points at product. The board is being told we are shipping faster than ever in the same quarter that renewals have started falling.
The Pole B move arrives through a customer advisory board. Several customers on the board, on separate calls, name the same pattern: the product has grown surface area faster than they can absorb it. The features they asked for two years ago are buried under features they didn’t ask for, and the team they originally trained on the platform has churned. The outcome is being eaten by their accumulation.
The retrospective surfaces the structural problem. Every feature shipped had been valuable, usable, feasible, and viable at the time it was scoped. Nobody had re-evaluated it against the integrated product experience.
Apple is the clearest counter-example I know. A pair of AirPods is not judged on its own feature list. It is judged on what happens when the same person picks up a phone, then a laptop, then a watch, and the audio follows them without anyone even touching a button. That is a test applied to the whole. Applied feature by feature, as this team applied it, the four-part test can tell you a feature is locally optimal; it says nothing about the whole it joins.
The fix wasn’t to abandon shipping. The team introduced a quarterly outcome review alongside the existing roadmap review and asked, for each major feature shipped over the past four quarters, whether customers were using it, whether that use produced the outcome the feature was supposed to deliver, whether the maintenance cost still tracked the value, and what customers could now do end to end across the product.
Half the features failed the test. A third were deprecated. The next quarter’s roadmap was leaner, and the cohort that had been churning steadied.
The engineering leader running the original output count wasn’t a bad leader. The previous CEO had measured them on output. The investor decks had measured them on output. The internal performance reviews had measured them on output. The system around the leader had reinforced Pole A for years.
So name what the discipline got the team—predictable cadence, investor confidence, a high-trust engineering culture—and then name what the new conditions required. The leader needed a different measurement system, and time to adjust to it.
The diagnostic
Three questions for last Tuesday’s launch celebration.
- Which pole was I claiming? In the language I used about the launch, did I name what the customer would now be able to do, or did I name what the team had shipped?
- Which pole did the team’s behaviour show? Look at where the team’s attention went in the week after the launch. Did it go to customer use or to the next item on the roadmap?
- Which pole does the work actually require? If output and outcome track tightly in your domain, Pole A is legitimate. If you are shipping more and the customer outcomes are flat or worse, Pole A has stopped being a proxy and started being a substitute.
The board deck often locks in this distinction. Whether the CEO or CTO owns the page, the metric used to describe engineering shapes incentives below. If you run engineering, the metric your CEO uses to describe your function to the board governs the output-versus-outcome question.
Put the metric that currently judges your function beside the metric that tracks customer progress. In most software-dependent organisations, these are different numbers. A CEO who describes engineering to the board in features-shipped vocabulary creates Pole A incentives three layers down, usually without intending to.
Ask for one sentence in the next board update that names what customers can now do, not what the team shipped. That is Pole B at board level. The team will read the update.
Give your CEO this sentence: “This quarter [N] customers began to [do the job] for the first time; from [next quarter] that count replaces features shipped in this report.”
The exercise
Rewrite a recent feature as a job to be done. Christensen’s test is specific: a job is the progress a person is trying to make in a particular circumstance; state it in verbs and nouns, and check that candidates for the job come from different product categories.
The job-story template—“when [situation], I want to [motivation], so I can [expected outcome]”—is a usable scaffold. It comes from the job-story tradition, not from Christensen. The format forces the team to name what the customer is hiring the feature for.
Notice how often the feature solves the firm’s job rather than the customer’s. When my quarterly performance review is approaching, I want to ship a visible feature, so I can demonstrate productivity to my manager is a job. It belongs to the employee, not the customer.
Run a companion vanity-vs-actionable metric audit. List your top five metrics. Mark each as vanity (it goes up regardless of whether anything is working) or actionable (you can trace what moved it, and it changes what you do). Defend each judgement to the team.
The usual engineering ones rarely survive it. Velocity moves whenever estimates move, and stories shipped is the same count in different units. Utilisation is worse than either: queues lengthen as it rises, so a high number is as likely to be a warning as a win.
If leader-follower dynamics turn out to be your live axis, run Marquet’s “I intend to…” protocol for a week. Chapter 17 lays out the full version. Even one week of replacing “request permission to…” and “recommend that we…” with “I intend to…” shifts who carries the cognitive load of the decision; run it and watch where decisions get made.
Going upstream
In-text: Clayton Christensen, Competing Against Luck, on Jobs to Be Done; David Marquet, Turn the Ship Around! and Leadership Is Language, on redwork and bluework and the language of intent.
Also touched: Eric Ries, The Lean Startup, on innovation accounting and vanity metrics; Douglas Hubbard, How to Measure Anything, on the test that a measurement only earns its keep if it changes a decision; Marty Cagan, Inspired, on valuable / usable / feasible / viable; Jeff Patton, User Story Mapping, and the talk Output vs Outcome & Impact (11 min, watch); Amy Edmondson, Right Kind of Wrong, on the four criteria for intelligent failure (developed in chapter 10).
Go deeper: Chip and Dan Heath, Made to Stick, on commander’s intent in organisational-messaging terms; USMC, MCDP-1 Warfighting, Ch 4, on mission tactics and commander’s intent; Frederick Taylor, The Principles of Scientific Management (1911), on the planning/doing division Marquet recasts as bluework and redwork; Alan Klement, Replacing the User Story with the Job Story (2013), on the job-story form, which originated at Intercom.
Manage to outcomes and some of them will miss. Watch what you defend when yours does. The call you made was a testable bet; the thing you protect in the review is usually your identity, and the second job eats the first. In chapter 10 you sit with that review, the one after a decision fails, and ask what the miss costs you next time: whether you spend it shielding the person who made the call or finding out what the call was worth.
I work with CTOs and CPOs at software companies with roughly 25–500 engineers, where the engineers are faster with AI and the business isn’t yet seeing the full value. When the team ships more and customers are no better off, I help leaders judge engineering by what customers can now do, and report that to the board. If it’s live for you, book a free 30-minute call at hi.chrisgagne.com and bring the one question that would make it worth your time. If you know a CTO or CPO in that spot, pass this chapter on. If you’d rather read on than talk, the newsletter goes on past chapter 23, monthly, at https://www.linkedin.com/newsletters/come-prepared-to-die-7472144387981062144/
Some book links here are Amazon affiliate links; if you buy through them I may earn a small commission, at no cost to you.