Analysis vs recognition: Keep the expertise your engineers need to catch AI’s mistakes
You list five options, score them against criteria, and pick the highest scoring. The experienced operator already knew what option to choose, their skill long since dropped below conscious thought. You’re slower and you’re no more accurate. Nothing is wrong with the analytical method; it was simply aimed at the wrong decision.
Chapter 12 named the capacity to disagree with a confident voice. Recognition is the cognitive-science version of the same question: when expert intuition is reliable, and when it is bias dressed as competence. It’s also where this book turns on the AI tools themselves: the second half asks what they do to the judgement you’ll need on the day they’re wrong.
The two poles
Pole A: analysis. The right answer comes from listing the options, comparing them against criteria, and choosing the best. Deliberate analysis makes a decision defensible.
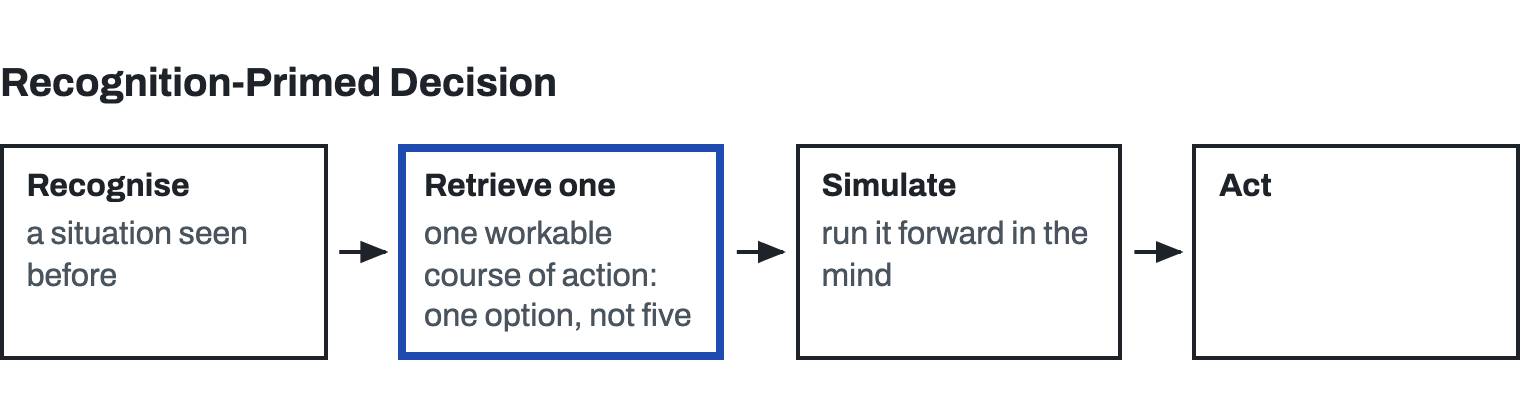
Pole B: recognition. The experienced operator recognises a situation they have seen before, retrieves one workable course of action, and mentally simulates it forward. It often arrives as a feeling before a thought, the gut that says roll back before you could say why. Pattern recognition makes a decision fast and—under the right conditions—reliable.
Where Pole A is right
Pole A is right when the environment is irregular, feedback is delayed or absent, the decision will need to be justified in public, or the operator lacks the experience that Pole B needs. Think of a CFO presenting capital allocation to the board, a new engineering manager making their first architecture call, or anyone facing a failure mode nobody has seen before.
Analysis is a good approach in those settings. The reader analysing a new acquisition, a new market, or a never-seen failure mode is doing the right work. For the engineering leader spending the day on AI governance, never-seen failure modes, and calls that will be justified in public, sustained analysis is the right choice. Recognition keeps the ground it has earned.
Honour where the analytic habit came from. A leader who came up justifying every call to a board, an audit committee, or a regulator built a real discipline, one that earns trust with other people’s money and works well for the decisions it was built to serve. The error comes when that discipline crosses into a domain where a calibrated expert’s first read is the better instrument and further thought buys delay and false confidence.
Where Pole B is right
Pole B is right when the environment is regular enough for experience to build trustworthy patterns and feedback arrives quickly enough to keep those patterns calibrated. Emergency response and surgical theatre fit. So does a deployment rollback that an expert has handled a thousand times, with the result visible within minutes.
In decisions
Pole A leaders use a checklist or formal review where the stakes are high and feedback is poor. Pole B leaders trust the experienced operator’s first reasonable option, while watching for the moment the situation slips beyond the operator’s experience.
Recognition owns a real but bounded territory: well-characterised, fast, recoverable judgements that an expert has made a thousand times. Analysis owns the rest, including the never-seen failure mode, the call the board will see, and the AI-governance decision that often sits behind both. Most of a senior leader’s hardest calls now sit there.
A CTO or VPE should carry one irony to the CEO on a single page: as AI takes over routine recognition, it erodes the very expertise operators need to catch its mistakes. The organisation’s approach to analysis and recognition decides how it governs AI tooling, and that governance belongs with the CEO.
The CEO needs to fund ways to preserve hard-won human expertise (deliberate practice, red-team exercises, and rotation of experienced operators through the edge cases AI handles least well) even when the dashboard is green. The budget won’t protect that work without a CEO-level signal. The sentence your CEO can carry to the board: “Automation is eroding the very expertise we’ll need on the day it fails.”
The Klein-Kahneman agreement
Gary Klein and Daniel Kahneman came from rival camps on when expert intuition can be trusted. Klein had documented it in firefighters, nurses, and chess masters. He called the mechanism Recognition-Primed Decision: the experienced operator recognises the situation as a type they have seen before, retrieves one workable course of action, and mentally simulates it forward (Klein, Sources of Power). Recognition makes the decision fast by replacing the comparison of options.
Daniel Kahneman had spent decades synthesising evidence against reliable intuition in stock pickers, political forecasters, and clinical psychologists. Confidence in those settings tracked the coherence of the story rather than the quality of the evidence. On the surface, Klein and Kahneman couldn’t both be right.
They eventually agreed in a 2009 American Psychologist paper titled Conditions for Intuitive Expertise: A Failure to Disagree. Expert intuition is real where the environment is sufficiently regular to be predictable and the operator has had prolonged practice, with feedback, at learning its regularities. Outside those conditions, confidence is not evidence that intuition is reliable.
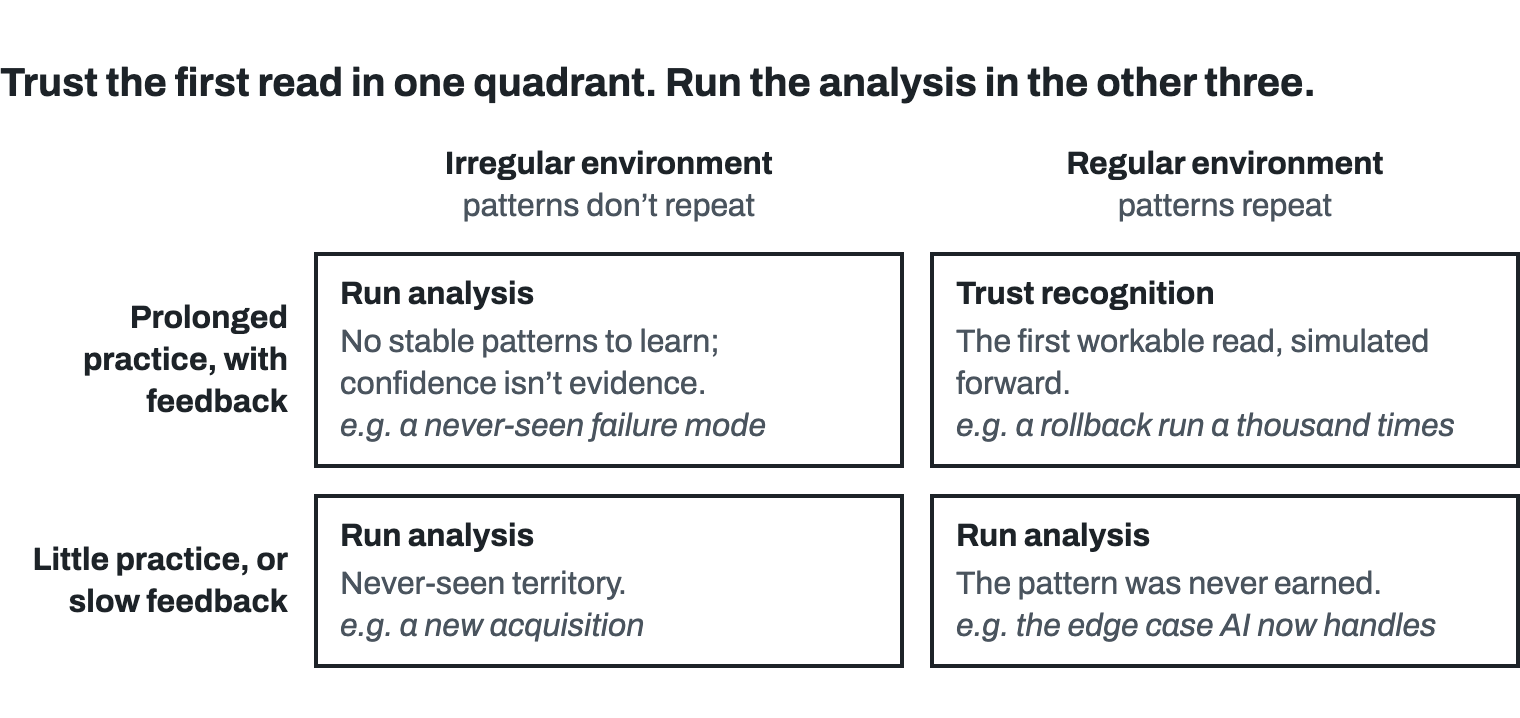
The conditions decide which pole fits. Ask whether they have produced reliable expertise.
Most organisations I have worked with ask whether the person making the call is senior enough. The Klein-Kahneman agreement asks whether the conditions have calibrated their recognition.
I recalibrate my own mentoring on this: the same misfire turns up in clients whose recognition was built in a context that has since changed.
Klein’s method underneath the framework
Klein reached Recognition-Primed Decision through fieldwork. His Critical Decision Method, a form of cognitive task analysis, asks experienced operators about recent hard incidents. The interviewer follows the story and probes the thinking: what did you see?, what made this familiar?, what would someone with less experience have done?
In regular environments, experienced operators usually retrieved one option, simulated it, and acted. They didn’t generate a set of alternatives. Herbert Simon had named satisficing decades earlier as a cognitive limit: taking the first option that meets the relevant criteria rather than maximising across all of them. Klein showed when that limit becomes an achievement: in regular environments, under time pressure, the expert takes the first workable option and acts.
A senior site-reliability engineer who calls a rollback in 15 seconds may be doing exactly what experienced operators do in regular environments with rapid feedback. A manager who makes them stop and list five options imposes Pole A on a Pole B situation, slowing the decision without improving it.
Distributed cognition
Recognition reaches beyond the individual. Cognition is distributed across people, tools, and the environment. In Edwin Hutchins’ study, a ship’s navigation team is one cognitive system, with the navigator working as part of a wider whole. When something fails on the bridge, the configuration that brings the ship to anchor includes the charts and instruments, the bearing books and trained crew, and the procedure for fixing position.
Remove just one component and the system can no longer think in quite the same way.
Engineering organisations also hold expertise across a system. The senior engineer who knows the legacy code depends on source code, a build pipeline, and an on-call playbook; none carries the whole capability alone. Pole A leaders sometimes ask individual engineers to compensate for a poor configuration through more analysis. Pole B leaders improve the configuration itself with better tooling, documentation, and playbooks, so the system carries more of the work.
The operator is part of the system, so blaming them treats one component as though it were the whole. Chapter 14 takes that claim out of cognitive science and into safety.
Bainbridge’s ironies of automation
Forty years before AI agents, Lisanne Bainbridge’s five-page 1983 paper, Ironies of Automation, named the cost of letting the machine do the easy parts: the central mechanism behind the recognition-versus-analysis choice in AI-augmented systems.
In the first of Bainbridge’s two ironies, the designer who tries to eliminate the human operator is also a potential source of system failure. In the second, as Bainbridge put it, the designer who sets out to remove the operator still hands that operator whatever the designer couldn’t work out how to automate, so the operator ends up with a leftover, arbitrary set of tasks that nobody designed support for. Automation strips the easy parts and leaves the hard ones. Then it gives the operator little help with what remains.
Automation strips the easy parts and leaves the hard ones. Then it gives the operator little help with what remains.
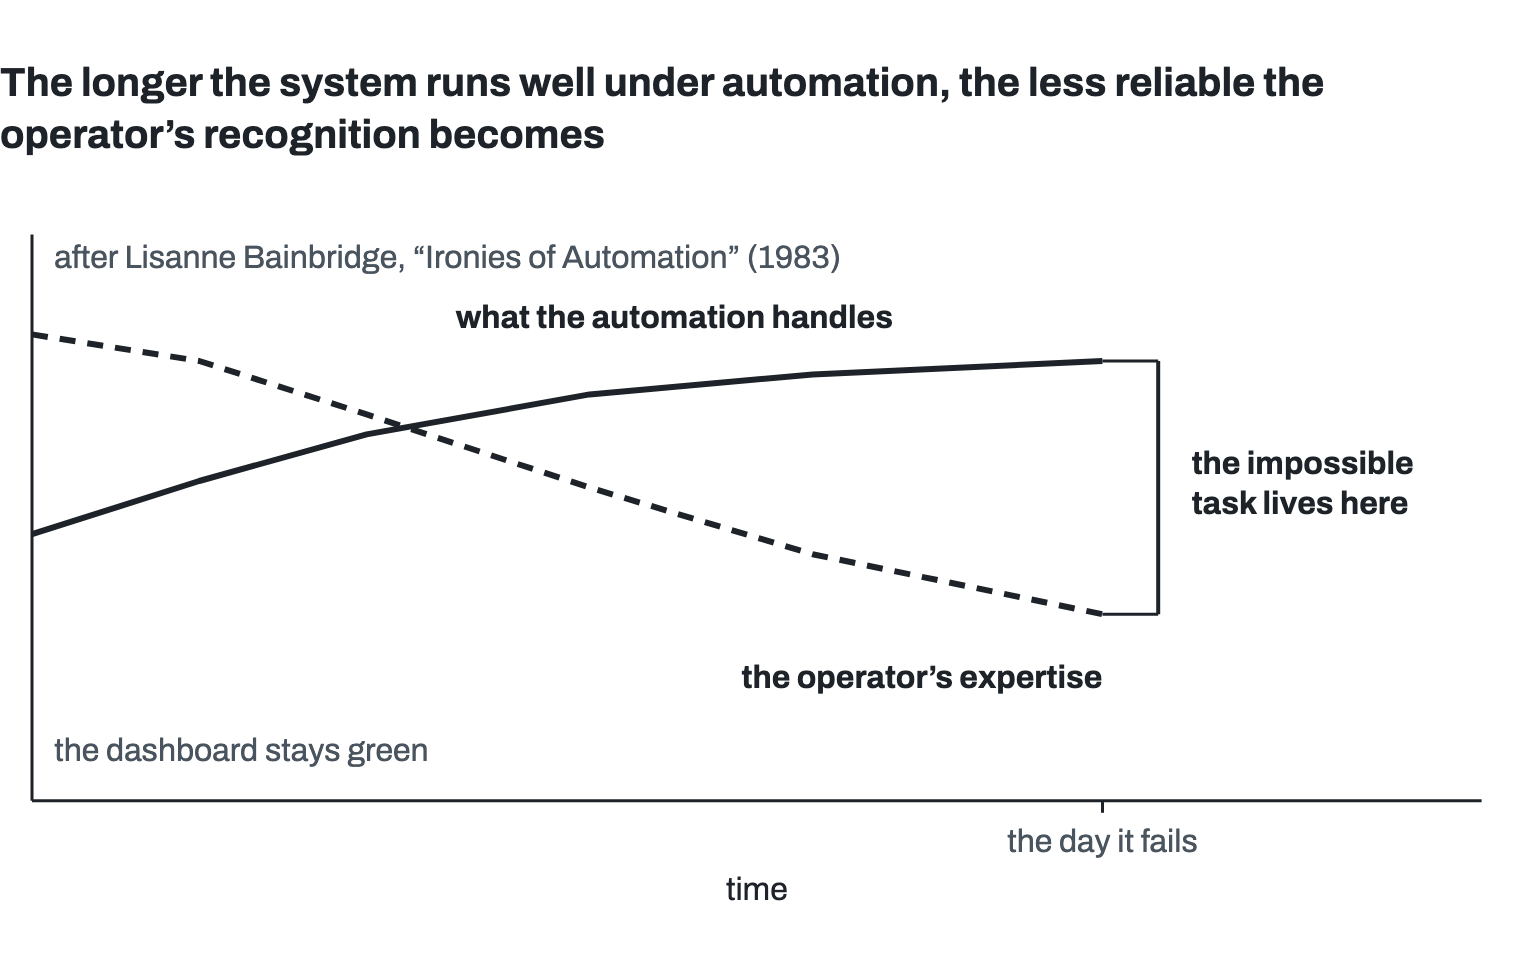
Bainbridge catalogued the effects: physical skills fade without use, so a formerly experienced operator who has spent long enough monitoring an automated process may now be an inexperienced one. Cognitive skills also need frequent use and feedback; once automated, they lose the patterns recognition depends on.
Working storage is Bainbridge’s term for the operator’s running feel for the process, richer than short-term memory, and it takes time to build. She noted that some manual operators enter a control room a quarter to half an hour before they are due to take over control so they can recover that feel. The central irony remains: the automatic control system is installed precisely because it outperforms the operator, and yet that same operator is the one charged with monitoring whether it is working.
Her verdict, in her words: “The human monitor has been given an impossible task.” The operator must catch what the automation misses in a domain where the automation already outperforms them on routine cases. Meanwhile, the automation has hollowed out the expertise built under the conditions Klein and Kahneman agreed produce reliable judgement.
The human monitor has been given an impossible task.
Lisanne Bainbridge, Ironies of Automation, 1983
Bainbridge’s irony of manual takeover follows the same mechanism: by the time a human has to take over, something has usually gone wrong with the process, so controlling it calls for unusual action, and you can argue the operator at that moment needs to be more skilled and less loaded than average, not less skilled and more loaded.
At the moment of need, the operator is less skilled and more loaded than they were before automation took the routine work.
My read is that Bainbridge’s 1983 mechanism explains AI governance better than most contemporary work: automation weakens the expertise it still depends on. The problem is older than ChatGPT. From the evidence I’ve seen to date, we mostly don’t have any better answers than we did in 1983.
Pole B recognition works only when the operator has the orientation the situation needs. Automation that strips away the operator’s experience degrades the conditions that make Pole B trustworthy. The longer the system runs well under automation, the less reliable the operator’s recognition becomes, until the moment something goes wrong and the system needs that recognition most.
The AI failure modes Bainbridge is pointing at
Frequency-versus-truth is the first failure mode. A large language model predicts the next token from statistical patterns in training data. Its output tracks the distribution of that data more than the truth of any claim. The training distribution is dominated by the average of what humans have written. That pulls the model toward the average consultant’s answer, the regression chapter 1 described, not the contrarian signal that makes a diagnosis valuable.
The model reproduces common errors with confidence; by analogy with Kahneman’s finding in people, its confidence tracks coherence of story, not quality of evidence. This is the Kahneman side of the Klein-Kahneman agreement applied to the system itself. Chapter 1’s grounding argument is the response, though the leader can’t always tell from the output whether grounding is in play.
Out-of-distribution collapse is the second failure mode. AI models perform well on tasks that resemble their training data. They degrade, sometimes gradually and sometimes abruptly, on tasks outside it. The model’s confidence doesn’t track its accuracy across this boundary; the output looks the same whether the task is well within the training distribution or well outside it.
Karpathy’s jagged intelligence from chapter 3 names the pattern: strong on one task, near-useless on a neighbouring one, with no visible seam between them. It produces plausible-looking code outside its distribution, the code fails contract tests the model was never given, and the operator ships it on trust without running the check.
Bainbridge expertise-hollowing is the third failure mode. An engineer who hands straightforward problems to the model keeps responsibility for the hard ones, exactly as in Bainbridge’s manual-takeover scenarios. At the same time, the engineer loses the practice needed to handle those hard problems: the pattern recognition built by solving easy cases and the feel for normal that makes abnormal recognisable.
The automatic system was put in because it performs better on routine tasks, but the engineer must still catch the cases where it fails. At the moment of need, the engineer is less skilled than they were before handing the routine work over.
A worked example: the experienced incident commander
The clearest version I have on record came out of an incident review. A whole group of users logged on one morning and couldn’t do their jobs. Within two minutes of the bug being raised, a senior engineer named the cause: duplicate user records, each person now holding two accounts, only one of them wired into the workflow they needed. They tested it on a single account first, deleting one duplicate and checking that person could work again. They could. The rest were cleared inside twenty minutes. They didn’t list five hypotheses and score them. They recognised the pattern.
Recognition did the work analysis would otherwise have had to do, and the conditions made it safe to trust: a senior engineer had the pattern, the single-account test gave feedback within minutes, and testing one account first kept the cost of a wrong read small.
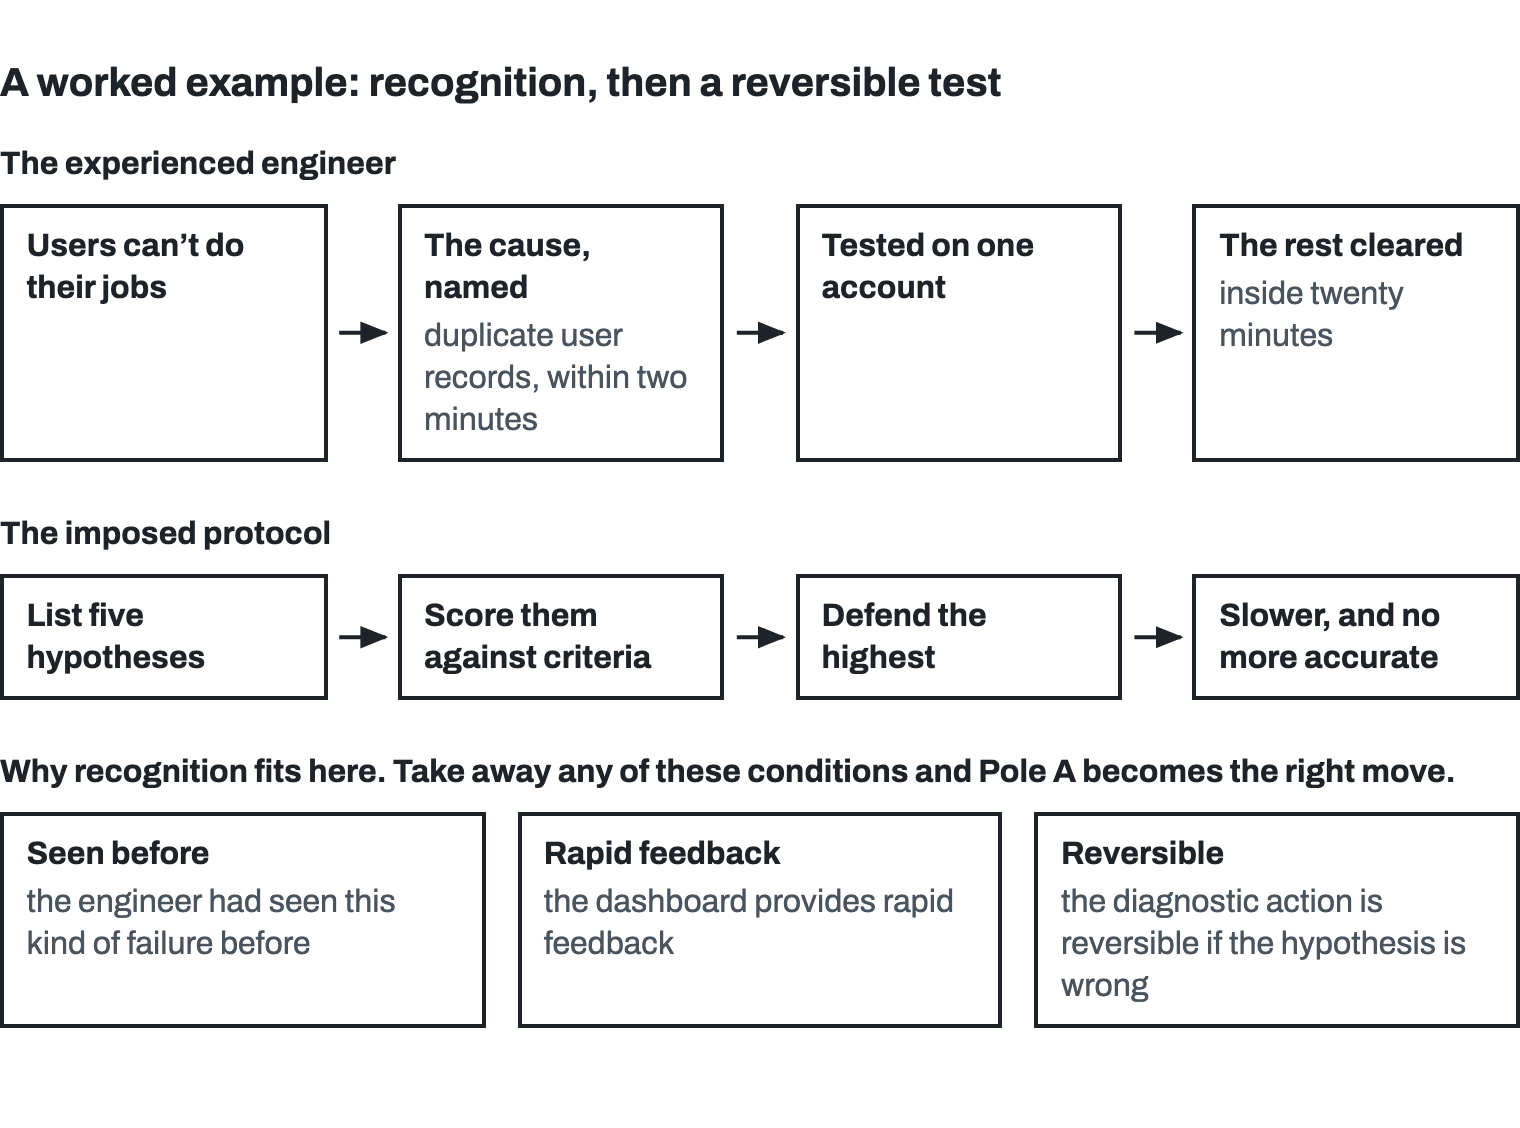
Take away any of those conditions and Pole A becomes the right choice. A newer engineer may lack the pattern. An under-instrumented environment can’t give quick feedback. An irreversible diagnostic action makes a wrong first read too costly. In those cases, the Pole A leader is right to ask for a checklist. Where the conditions support recognition, the Pole B leader is right to let the engineer decide.
Recognition can also point confidently at the wrong layer. In another incident a whole floor lost a screen they needed, and the failure read as infrastructure: about five hours went into the cluster, the pods, and DNS. The cause was a content-filtering policy on the office network blocking the domain. The wrong read held because the monitoring couldn’t see the problem: the health checks ran from inside the cluster, so they never crossed the firewall doing the blocking. The environment wasn’t supplying the feedback that makes recognition trustworthy.
The AI overlay
AI agents work like recognition machines: they identify patterns in training data and produce outputs that match. ITIL split the question in two a long time ago. Utility, what a thing does, has never been cheaper and is heading towards free; warranty, the assurance it will keep doing it well enough to depend on, is getting more expensive. In an engineering organisation that reads: writing the code got cheaper; ensuring it is accurate, secure and reliable didn’t. Utility is Pole B territory, where the work resembles what the model has seen and the output can be checked fast. Warranty is Pole A work, and Bainbridge’s irony is much of why it now costs more.
Deploying AI in Pole A territory and trusting its confident outputs is a structural mistake. The model may have few relevant patterns to recognise there, so coherence of story masquerades as expertise. The Kahneman side of the Klein-Kahneman agreement applies to models as it does to people. Confident output without environmental regularity is bias.
As in Bainbridge’s ironies, when AI handles routine recognition well, the human operator loses the practice needed to catch the cases it gets wrong. Governing AI therefore calls for two disciplines: analysis for the irregular calls, and keeping human expertise alive while automation does most of the routine work. Chapter 17 returns to this AI-and-authority question.
The recognition story still holds within a smaller domain than the one a senior leader now inhabits. Once AI is in the loop, the human must keep a live, independent read on the automation because its confident output is least trustworthy in irregular territory. Sustained analysis is the governing discipline.
My coding agents build an open-source library from specifications I write. Its pre-push check for private data didn’t run whenever a change was pushed from the workspace where the agents work, and nothing told me it hadn’t. By the time I found and closed the gap, one pending change had already named a private source, though nothing private was published.
A leader governing AI well first identifies which decisions fall in regular environments, where AI recognition is reliable, and gets out of the way. For irregular environments, the leader uses analysis, checklists, and formal review; most consequential calls belong here. The leader also preserves the expertise automation would otherwise erode through deliberate practice, red-team exercises, and rotation through edge cases, so the human keeps an independent read on whether the automation is wrong.
One of those three is Pole A work: formal review for the irregular calls. The deliberate practice that keeps human judgement sharp is investment in the expertise both recognition and analysis need. Applying one method to all of them is bad governance, so the discipline is routing by conditions rather than a standing default. For the AI-governing reader, the irregular calls are where the stakes sit, so that is where analysis earns its place.
The diagnostic
Three questions for last Tuesday’s decision:
- Which pole was I claiming? Did I treat the decision as one for analysis or for recognition?
- Which pole would the actual decision-process show? If a colleague watched the process, would they see deliberate option-comparison or experienced-operator recognition?
- Which pole did the conditions actually support? Regular environment, rapid feedback → Pole B. Irregular environment, delayed feedback → Pole A. Automation-mediated environment that has hollowed out the operator’s experience → Pole A safeguards for the call, regardless of what the operator’s stated experience suggests, plus practice to rebuild the expertise analysis needs too. Automation-mediated calls are becoming common enough that a leader whose work is increasingly AI-mediated should test for hollowed-out experience explicitly, which is why analysis is the preferred approach for that reader.
In my experience, the most common gap is between the second and third questions. Leaders trust recognition in conditions that don’t support it, or apply formal analysis where the experienced operator already knew.
The exercise
Run a Klein-Kahneman conditions check on a decision your team is sitting with this week. Ask two questions aloud. Is the environment regular: has the person making the call seen many cases like this one, with the same cues? Is feedback rapid and clear: did those past cases tell them, within days, whether their call worked?
If both answers are yes, trust the experienced operator’s recognition and get out of the way. If either answer is no, run an analytic protocol.
Then try the check on a decision the team has already made and is now defending. Where the check turns up a no answer on a defended decision, the operator’s confidence may have outrun the conditions; look into it. Naming that without blame builds the check into the team’s practice.
Going upstream
Watch. Daniel Kahneman video, Thinking Fast vs. Thinking Slow (Inc. Magazine, 7 min). Companion: Gary Klein, NDM/RPD video, Introduction to NDM and RPD (9 min).
In-text: the central pair and the AI overlay. Gary Klein, Sources of Power; Daniel Kahneman, Thinking, Fast and Slow, on the Kahneman-Klein agreement (the 2009 American Psychologist paper Conditions for Intuitive Expertise: A Failure to Disagree). For the AI-automation irony 40 years early: Lisanne Bainbridge, Ironies of Automation (1983; 2021 retrospective preface available online).
Also touched: Herbert Simon on satisficing, Models of Bounded Rationality. Edwin Hutchins, Cognition in the Wild, for the ship’s navigation team (the USS Palau) as one cognitive system. ITIL (AXELOS) on utility and warranty.
Go deeper: the same recognition claim arrives from several further traditions, none anchored in the body above. For the OODA loop and orientation as the central node: Robert Coram, Boyd: The Fighter Pilot Who Changed the Art of War (and Boyd’s appendix essay Destruction and Creation; Fingerspitzengefühl, fingertip-feel). For the doctrinal statement of Pole B: USMC, MCDP-1 Warfighting, Chapter 4. For joint cognitive systems as the unit of analysis: David Woods and Erik Hollnagel, Joint Cognitive Systems. For the wider bounded-rationality lineage the chapter inherits: James March, A Primer on Decision Making. And from the emotional-intelligence tradition, for the felt and bodily side of recognition a purely analytic read can’t reach: Karla McLaren, The Language of Emotions, on the four intelligences (analytical, emotional, somatic, visionary) and the cost of letting the intellect try to rule without the other three.
One of the operators automation leans on and wears away eventually slips, and you open the incident review to name the rule-breaker who caused it.
You find one.
The deviator was doing what the system trained them to do, so the report you sign punishes a person and leaves the conditions loaded for whoever fills the role next. In chapter 14, you pull the punishment off the person and put it back on the conditions.
I work with CTOs and CPOs at software companies with roughly 25–500 engineers, where the engineers are faster with AI and the business isn’t yet seeing the full value. As AI takes over routine work, engineers lose the practice that catches its mistakes, so I help leaders choose which calls need review and keep that skill alive. If it’s live for you, book a free 30-minute call at hi.chrisgagne.com and bring the one question that would make it worth your time. If you know a CTO or CPO in that spot, pass this chapter on. If you’d rather read on than talk, the newsletter goes on past chapter 23, monthly, at https://www.linkedin.com/newsletters/come-prepared-to-die-7472144387981062144/
Some book links here are Amazon affiliate links; if you buy through them I may earn a small commission, at no cost to you.