[May 2026]The safety frame I’m reaching for here is what Edmondson formalises as psychological safety and what Dekker grounds in just-culture. Modern Agile’s “safety as prerequisite” has matured into a richer literature on near-miss reporting, blameless inquiry, and learning-organisation discipline.
[August 2026]What the handbook shows is a company that changed the conditions rather than exhorting people to try harder inside the old ones. The line I quote here, “You just don’t see the line stop,” is the contrast Chapter 6 of Come Prepared to Die builds on, where I set NUMMI against Deming on tampering and Seddon on failure demand, and treat a Definition of Done as an andon cord.
Standing on the shoulders of giants, I reached out to the archivists at the library to see if I could get a copy of the full handbook. They cheerfully obliged, and rather quickly at that!
Grab the PDF and peruse for yourself. The first several pages are the most interesting, but even as you explore the rest of it pay attention to how human and reasonable it is. Mark provides an excellent commentary on several key sections, so I’ll try to avoid highlighting the same thoughts. I hope you’ll share your own findings and commentary in the comments below.
Here are some of the gems I’ve found:
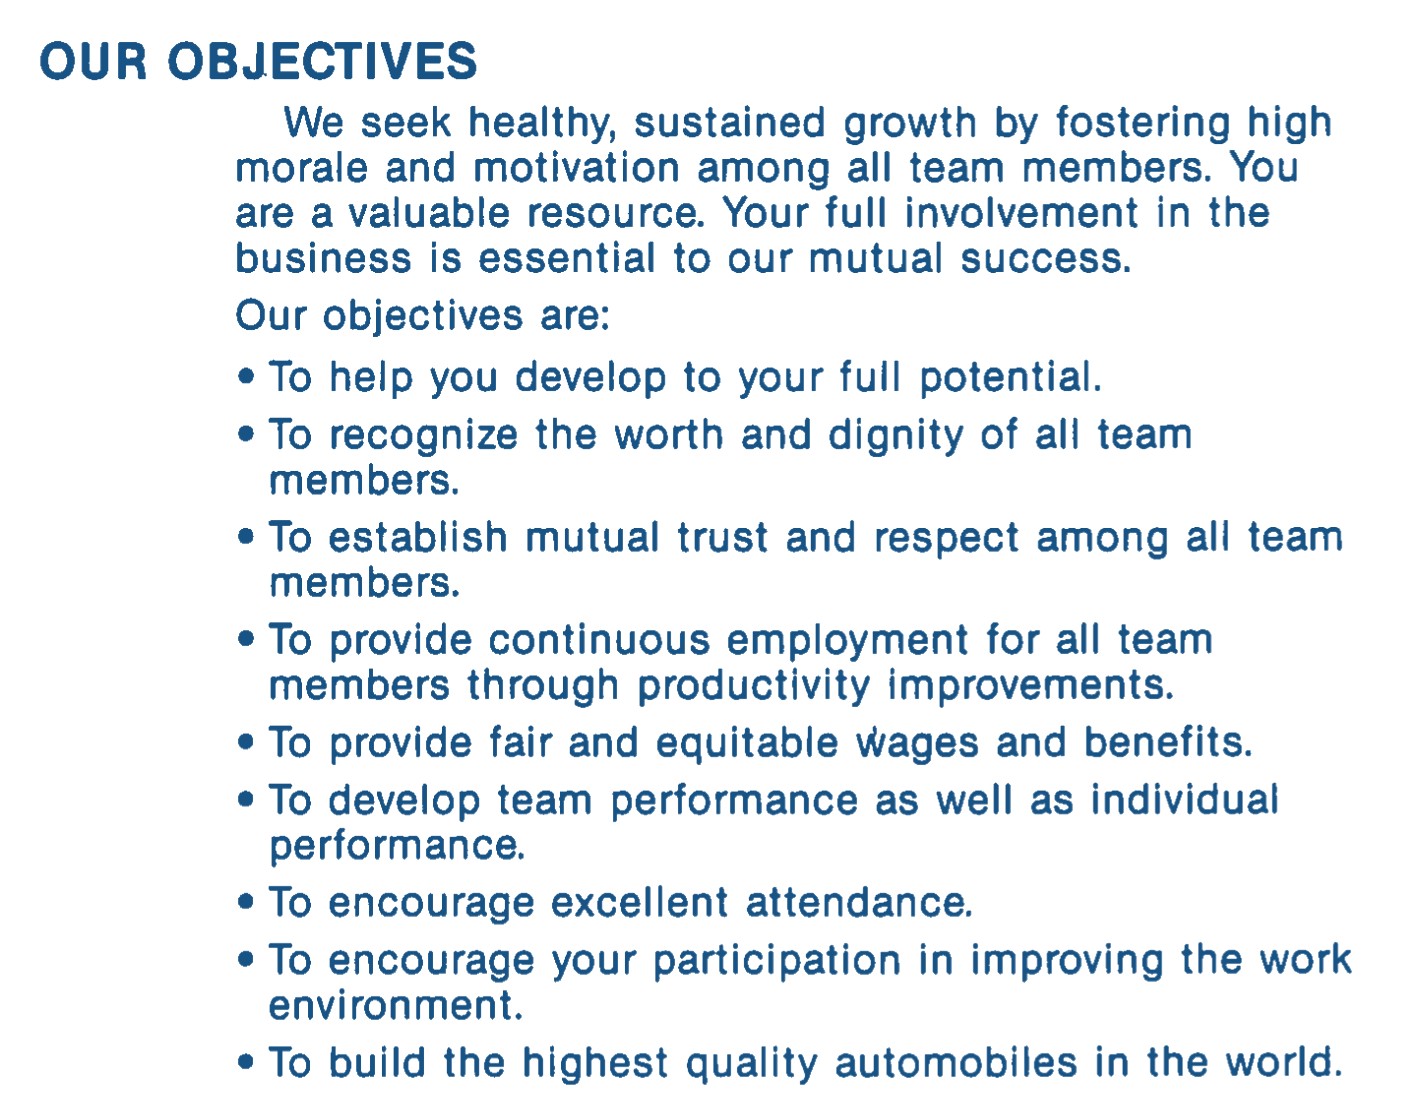
Notice that the first objective is “To help [employees] develop to [their] full potential.” In fact, these objectives start with the individual employee, progress to the company, and then ultimately end with the customer receiving the “highest quality automobiles in the world.” This is a notable inversion from the usual objectives, which usually prioritize stakeholders and customers, then the company, then—if at all—the individual employee.
This is extraordinary in two ways. First, employees are given the expectation that they are going to have a greater autonomy and influence over how other aspects of the organization operate. I’ve heard the statistic that Toyota’s 300,000 global employees make a total of one million suggestions annually, 97% of which are implemented. Secondly, note that the employee handbook is characterized as helping the employee “do [their] job better,” a far cry from the usual purpose of this kind of handbook (protecting the company’s interest).
[May 2026]I now reach for Schein on culture, Westrum on generative-vs-pathological organisations, Edmondson on psychological safety, Senge on learning-organisation discipline, and Galbraith’s Star Model alongside Org Topologies for structure as the more rigorous current vocabulary for what this post calls “structure and culture.” The doing-vs-being distinction still holds; the toolkit has matured. I’ve also since added a fifth box at the cheap end of the diagram, to the left of tools: “terms,” changing the words you use. It’s the easiest change and the emptiest one, and I can’t claim much originality for it. Craig Larman named this years ago in the second of his Laws of Organisational Behaviour: any change initiative gets reduced to redefining or overloading the new terminology to mean basically the same as the status quo. New words, same operating model.
[August 2026]The NUMMI listening questions I set out here, about what changed in the plant and what GM could not replicate elsewhere, are the ones I work through at length in Chapter 3 of Come Prepared to Die. Same plant, read the other way round: the chapter takes NUMMI as the inverse case, where GM copied the production system and left the structure alone. AI now hands you the tools-and-process win almost for free, which leaves the structure you never touched as where most of the remaining gain sits. I came back to that plant from a different angle in the Team Member Handbook post.
Are you doing Agile, or have you become Agile?
The difference seems pedantic at first…
You are doing Agile when you’ve changed your tools and processes. This is relatively easy to do but doesn’t offer much in the way of benefits. You’ve becomeAgile when you’ve changed you structure and culture too. This is relatively hard to do, but offers significant benefits.
Agile isn’t just a process. It’s a complete framework that brings together a shift in culture, structure, and processes. This framework is supported by tools such as Rally and other Agile Lifecycle Management (ALM) tools.
[May 2026]I’d now call this the early Planned/Unplanned Velocity instinct. The 2014 practice (track unexpected requests and impediments as a separate signal) has matured into SPC control charts on the two streams (Shewhart, Wheeler) plus a displacement rule that triggers intervention when unplanned work crowds planned work; same instinct, sharper measurement.
[August 2026]The refusal at the heart of this post, that a team landing at 72% has told you something about its conditions rather than about itself, is what Chapter 14 of Come Prepared to Die works through. The chapter carries it into incident response, where hunting the operator who deviated leaves the conditions that produced the deviation untouched.
A team should be able to complete 80–110% of their planned stories each and every sprint without heroics.
Why is this important?
The work output from this team is predictable. When the team commits to a set of stories at the beginning of the sprint, other teams can rely on them to deliver.
Predictable output breeds confidence. If a team consistently delivers on their commitments, they are considerably more credible when they need to push back on unrealistic expectations.
The team will likely feel motivated because they’ve demonstrated a degree of mastery in their craft.
The team has a stable base. Because they are delivering on their expectations, they can focus their energy on continuous improvement and optimization.
If a team regularly completes less than 80% of their sprint objectives, why does this happen?
The work tasks do not meet INVEST criteria and thus cannot be estimated accurately.
New work is given to the team mid-sprint.
The team faces new and old impediments that interfere—usually unpredictably—with their ability to deliver the work.
It’s not always easy to glean these issues from tools like Rally. Thankfully, there’s a simple solution that can help both individual teams and the program discover the severity and nature of the issues that prevent a team from achieving fast, flexible flow.
The Status Quo
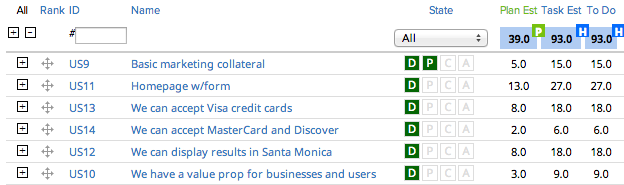
Let’s take the example of a 2-person team working a 2-week sprint. (This isn’t an ideal team setup, but it keeps the numbers easier to work with.) Here’s their sprint backlog a few hours after planning:
They’ve taken on 39 story points, which is one fewer than the 40 accepted story points they completed last sprint. That’s perfectly reasonable.
They’ve added tasks to each of these stories and began work on the first one.
I like to assume 6 hours/day of productivity per developer to account for planning meetings, standups, retrospectives, breaks, lunch, etc. Two developers * 2 weeks * 6 hours/day = 120 hours. Assuming a 25% “safety factor” (some teams use 30%, others use 20%, the truth is that we’re splitting hairs at this point), the team should be able to complete about 96 hours of planned tasks this sprint. They’ve identified 93, so this “smells” okay.
(Note: the team should use story points to gauge how much work to accept into the sprint backlog. Use the task hours as a sanity check.)
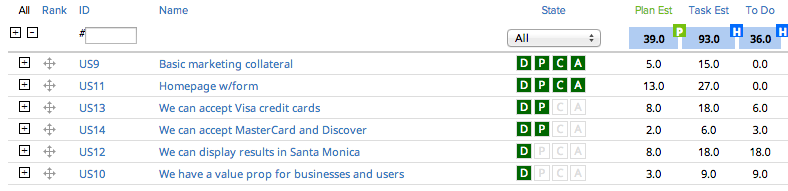
Let’s fast forward a week and a half. It’s Tuesday afternoon, and there are about 2-1/2 days left in the sprint:
The product owner accepted 18 points or 46% of the sprint. There’s 36 hours of work left and about 30 hours of time left, so we’re a little behind. Most novice Scrum teams would not register concern at this point.
What happened during the sprint? The development team raised impediments during the standup and worked through them. One developer was out sick for a day. The team had to go to an unexpected all-hands meeting, and they had to do a couple of side projects.
The problem is, there’s no measurement or record of these unexpected requests and impediments. The unexpected requests should not have been added mid-sprint unless they were (rare) “on-fire” issues. The team (and anyone who attended the standups) would know what the issues were, but this knowledge is limited or non-existing at the program level or higher.
This is a missed learning opportunity as we do not have the transparency we need to inspect and adapt.
Introducing the Unexpected Requests and Impediments Story
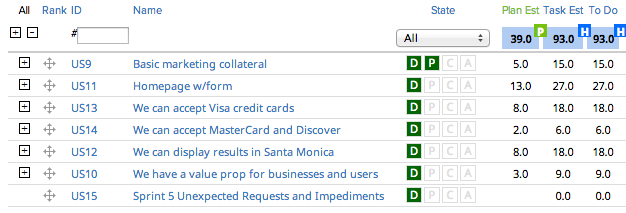
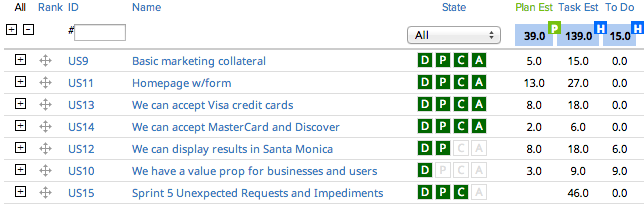
Let’s rewind and add a new story to the sprint backlog:
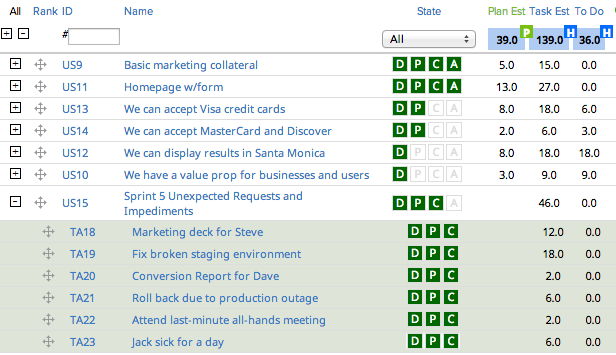
Note the addition of “Sprint 5 Unexpected Requests and Impediments” at the bottom. This doesn’t get story points and it’s at the bottom because it’s the last thing you want your team to be working on.
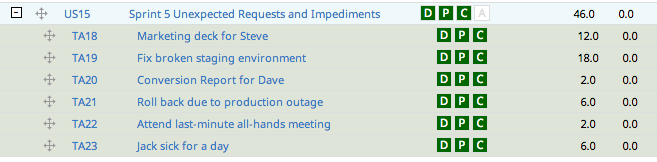
Each and every unexpected request or impediment gets added to this story as a task (with hours) during the sprint, like so:
Suddenly these side projects and impediments become real.
Let’s take a look at that mid-sprint view of the backlog again.
Suddenly, the problem becomes even more clear. We should be able to complete about 120 hours of work in a 2-person, 2-week sprint, but our task estimate is now up to 139. Unless this team works overtime (which they should not do as it is demotivating and ultimately productivity-killing), we’re not going to complete all of our stories in time for the demo.
So here’s where this team ended up right before their demo:
They completed 28 story points or 72%. A “pointy-haired boss” might look at this team and say “you failed.”
That statement in and of itself is a failure. It jumps to the conclusion that the team experienced a performance failure. In reality (with all credit due to Mary Poppendieck), the more likely failure is that of the original hypothesis: that the team could have completed the work in the first place. There’s a major missed opportunity: the opportunity to learn something from our system and adapt.
We budgeted 25% of our time for these sorts of issues, or 24 hours. We wound up with 46 hours of unexpected requests and impediments, 22 hours “over budget.” We had 15 hours of work remaining on the two stories we didn’t complete, so it’d be pretty reasonable to say that had it not been for those extra 22 hours of work, we would have completed this sprint (and perhaps even added a 1- or 2-point story).
Ideally, you’re keeping track of your velocity from sprint to sprint. Add another metric: keep track of the percentage of task hours each sprint that came from unexpected requests and impediments.
So what?
Now we have transparency. Transparency allows inspection, inspection allows adaptation. Here are some ways to use this information to inspect and adapt:
The team can review the impediments and suggest user stories to the product manager (often spikes or technical user stories) to help address some of the underlying technical impediments.
The team can use this as feedback that they may need to slow down and refactor to address technical debt. They may not want to create new user stories, but they should at least spend a little extra time on their new user stories to clean up old debt and avoid creating new debt.
The Product Owner can show stakeholders the cost of unexpected requests and impediments on their predictability. This gives them the evidence they need to hold off on new requests until the next sprint and spend more time building quality into the work that they are doing.
Engineering managers and program managers can review impediments across teams and look for impediment patterns to solve. For instance, an engineering manager may be able to quantify that the company spends 10-15% of their development time fixing broken environments. This data could justify an much-needed investment: “We lose $1M a year in productivity fixing broken environments [based on salaries multiplied by time lost]. A new VM system would reduce this cost by 50% and cost us $100K.”
There you have it. Regardless of the software you use (if any), you can add the Unexpected Requests and Impediments story to your sprint backlog. You can use the data it generates to gain knowledge and take corrective action.
What are your thoughts? Have you used something like this in your own team? Please share your thoughts!
[May 2026]I’d frame this more carefully now. Social-evaluative threat and Amy Edmondson’s psychological safety are close cousins, not the same thing: psychological safety is about whether people believe it’s safe to take interpersonal risks at work. And I’d treat Yerkes-Dodson as a useful heuristic rather than a hard law. The point I still stand by: lower the threat in the room, don’t push harder.
Work harder!
We’ve all been admonished to work harder at some point in our lives, whether it was from a well-meaning parent, a sports coach, or a manager facing a deadline.
What many Agilists have come to empirically observe is that the more we can get people to feel happy and have a good work/life balance, their total productivity goes up. We’ve come to learn that “busyness” is not productivity. I have heard managers brag of how dedicated their teams are because they’re working 100-hour weeks on their latest and greatest innovation. Yet they seem to miss the fact that had their teams spent 35–40 hours a week on their latest and greatest innovation, it would be less late and even greater.
So, why do some managers insist upon added stress and arousal? Clearly there must have been a time or place where “cracking the whip” made sense.
Hint: It’s not in highly creative fields like software development.
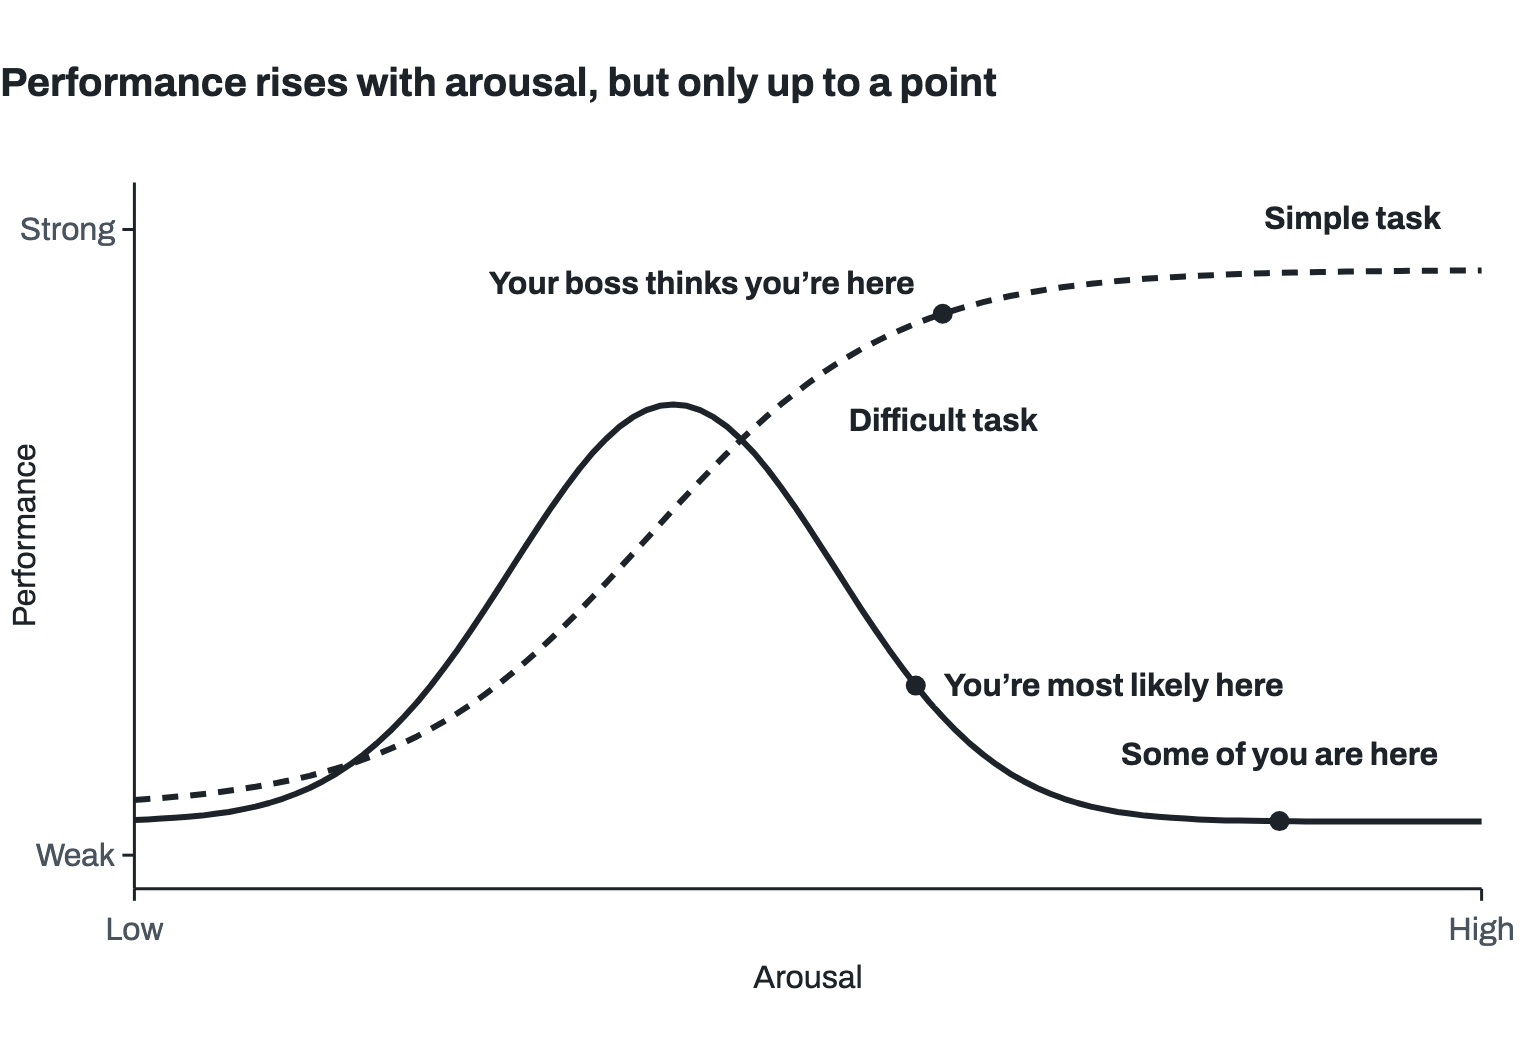
It turns out that there are some times when it makes sense. According to the Yerkes-Dodson law, an “empirical relationship between [physiological and mental] arousal and performance,” performance increases when arousal does but only up to a point. In some cases, further arousal lowers performance.
For simple tasks, more arousal equals more performance, at least up to a point at which it relatively plateaus. For difficult tasks, more arousal equals more performance, until it reaches a peak and begins to plummet at the rate that it rose. This is because stress negatively affects cognitive processes such as attention, memory, and problem solving, all critical for the modern knowledge worker.
Put another way…
Shapes only: the law describes a relationship, not a measurement. After Yerkes and Dodson (1908).
One of the things that I really like about Agile is that it’s all about staying empirical… Transparency benefits inspection, inspection benefits adaptation. And over the years, we’ve come to learn in the business context what many have learned in the psychology and biology contexts.
For instance, a 2007 review of the effects of stress hormones like glucocorticoids found that people’s performance on memory tests and the levels of stress hormones in their blood produced very similar responses to what Yerkes and Dodson found nearly a century earlier. One example: long-term memory formation followed the same inverted-U — best with a modest level of glucocorticoids in the bloodstream, and worse at either extreme, whether the adrenal glands were removed (no glucocorticoids at all) or extra glucocorticoids were injected.
Interestingly, this same review found that in order for something to induce a stress response, it has to be perceived as: novel, unpredictable, uncontrollable, and/or possibly leading to social rejection. Naturally, any knowledge worker’s office is likely to be plagued by novelty, unpredictability, and a lack of control (at least from external circumstances like competition).
One of the things Agile teaches is how to manage these constants well. Rather than stressing out and feeling like we need to “replan” because “things didn’t go the way we planned,” Agile assumes that things won’t go as planned. Uncertainty is embraced. Servant leaders who understand the nature of software development reality deeply understand these things, and so don’t unnecessarily create a culture of fear that produces the sense of a “social evaluative threat” when “the plan isn’t met.” The plan hypothesis was wrong in the first place.
Thus, workers in strong Agile cultures are more productive not only because they aren’t working 80-hour weeks, but also because the whole culture (especially the leadership) is mature enough not to freak out at every single change. These workers experience less stress, therefore they’re producing less stress hormones, and therefore their brain isn’t acting like it’s about to be eaten by a tiger. Keep in mind the tiny amount of time that has elapsed between the constant fear of violent death and the modern 72°F office environment, at least from an evolutionary perspective.
This is your brain on stress.
Truly Agile companies put people in environments where they feel autonomy, mastery, and purpose, providing strong intrinsic motivation, which doesn’t create the same kind of stress. Fear and command-and-control drive that out, and the people with the most options are the first to leave. Performance is shaped as much by the system around a team as by any individual in it: a culture of fear is a system problem, not a talent problem.
It’s easy to feel like a hero or a martyr when you’re working those eighty-hour weeks “for a cause.” Managers can tell their employees that they’re not “strong enough” and need to “man up” and put in the hours. But try as we might to ignore them, rarely can we escape the simple facts of our physiology and biology.
And if your own arousal is running past its peak right now: I built a two-minute breathing pacer for exactly that. Set a timer and try it.
Source note: the original 2014 version of this post leaned on Wikipedia’s overview of the Yerkes-Dodson law for the background.
[August 2026]Mary names a paradigm here that I’ve since written a book around, and she got there well before I did. Her claim is that a schedule rolled up from a work breakdown is a hypothesis dressed as a commitment. Chapter 7 of Come Prepared to Die works that axis and leans on this talk to do it, particularly her reading of Sapolsky on Polaris, where PERT turns out to have been a façade built to keep Congress paying. Her Empire State material runs the other way, toward Chapter 8. They had a fixed date, 1 May 1931, because that was when New York leases turned over, and on the day the contract was signed there was no design. The stone went up in 8 months. The job came in 18% under budget. The Empire State build is also the cleanest case I know for scheduling by flow rather than utilisation; I take that up in Utilisation vs Flow. If your plan keeps going nervous on you, the plan is likely the problem, not your team. Working out which one you have is most of the diagnostic I run. If you want this school of thought as a primary document, the 1984 NUMMI team member handbook shows the same thinking written for the factory floor.
Watching the video on the InfoQ website is a bit kludgey and Mary has lots of wonderful details that are worth hearing. So, with Mary’s permission, I’ve had the video transcribed and included her slides in context. I hope that this will make this very useful knowledge easier to find and learn from. Mary, thanks again.
I’ve eschewed block-quote formatting as it made this transcript a little harder to read. I’ve also edited slightly for readability. Otherwise, everything beyond this point is Mary’s work.
[May 2026]This argument still holds. Both “ship quickly and often” and “defer commitment” remain true today; cost-of-delay weighting (Reinertsen, Fox & Gregory) and real-options framing are the sharper economic vocabulary that grounds them.
[August 2026]“They build slowly and test often” is the practitioner’s version of an argument I make more formally in Chapter 7 of Come Prepared to Die: a plan held as a commitment kills the learning, and a plan held as a hypothesis invites it. The marshmallow is what a premature commitment feels like when it lands.
Spaghetti and Twine
Many of you will be familiar with Peter Skillman’s Marshmallow Challenge, an exercise frequently given to teams and business school students. Teams of four are given 20 pieces of spaghetti, 1 yard of tape, one yard of twine, and a marshmallow. They are then given 18 minutes to build a free-standing structure that places the marshmallow as high off of the table as possible. The team with the highest marshmallow wins.
If you haven’t seen it already, Tom Wujec’s TED talk is a good place to learn about the challenge. And if you haven’t introduced your team(s) to it, take 45 minutes out of one of your days to administer the challenge and see what revelations you get.
[May 2026]I still think rigid priority-number columns mislead, but I no longer believe the fix is sitting down with stakeholders to sort the list by hand. Today I’d weight by cost of delay (Reinertsen’s WSJF, Fox and Gregory’s economic framing) and treat ordering as a live conversation grounded in numbers, not as a one-time stack-rank artefact. The instinct toward relative priority was right. The toolkit was thin.
[August 2026]Cost of delay is the variable Chapter 4 of Come Prepared to Die names, and this 2008 post was reaching for it without the word. What I argue here is only that relative order beats absolute priority. The chapter adds the economics that argument was missing: in high-variation work, keeping everyone busy makes the system slower, and queues are what you are managing whether you know it or not. The Customer is the Marshmallow makes the companion argument: defer the commitment and test before you build on top of it.
More specifically, I hate numbers or letter representations of priorities when it comes to product backlogs.
It’s a common strategy, even in Scrum. (Henrik Kniberg’s wonderful scrum book talks about a product backlog where higher priority items get higher priority numbers, preventing the “if this is critical and priority 0, what is ultra-critical? priority -1” issue.)
So why the hate? Simple – they do a lousy job of actually priortizing tasks. How many times have you encountered a product backlog where there were several items that were all of critical importance? How is this truly helpful?
Think of it in this way – what if half the items in your email inbox were of CRITICAL priority? At this point, what value does this tag add? At the end of the day, you’ll have to choose ONE thing to do next. What will it be?
I therefore argue that it’s exactly this hard decision that needs to be made earlier in the process, with the stakeholders who will wonder why this critical priority issue took precedence over that critical priority issue.
The real issue is that priority values attempt to apply a rigid metric of ABSOLUTE priority when the only thing that matters in the real world is RELATIVE priority – what do we do next? Even if you have the ability to complete work in parallel (e.g., more than one developer), you still need to figure out what those n people will do next.
Therefore, I propose that we kill the concept of priority values in the agile workplace.
Take your product backlog, remove the priority column, and sit down with the stakeholders. Don’t walk out of the meeting room until every item is sorted in order of relative priority.
The rest is easy: in your next sprint planning meeting, figure out how many story points you have available and work down from the top of the list. There are only two exceptions:
When the developers believe that two pieces of work are similar enough to realize greater efficiencies if completed together. If this happens often, you need greater developer involvement in the priority setting meeting.
When the remaining story points don’t support the next priority item. For instance, suppose there are 3 remaining story points but the next item in the product backlog requires 5. It’s OK to scan down a little and take the next item at or below three points.